Skip to content

Blog

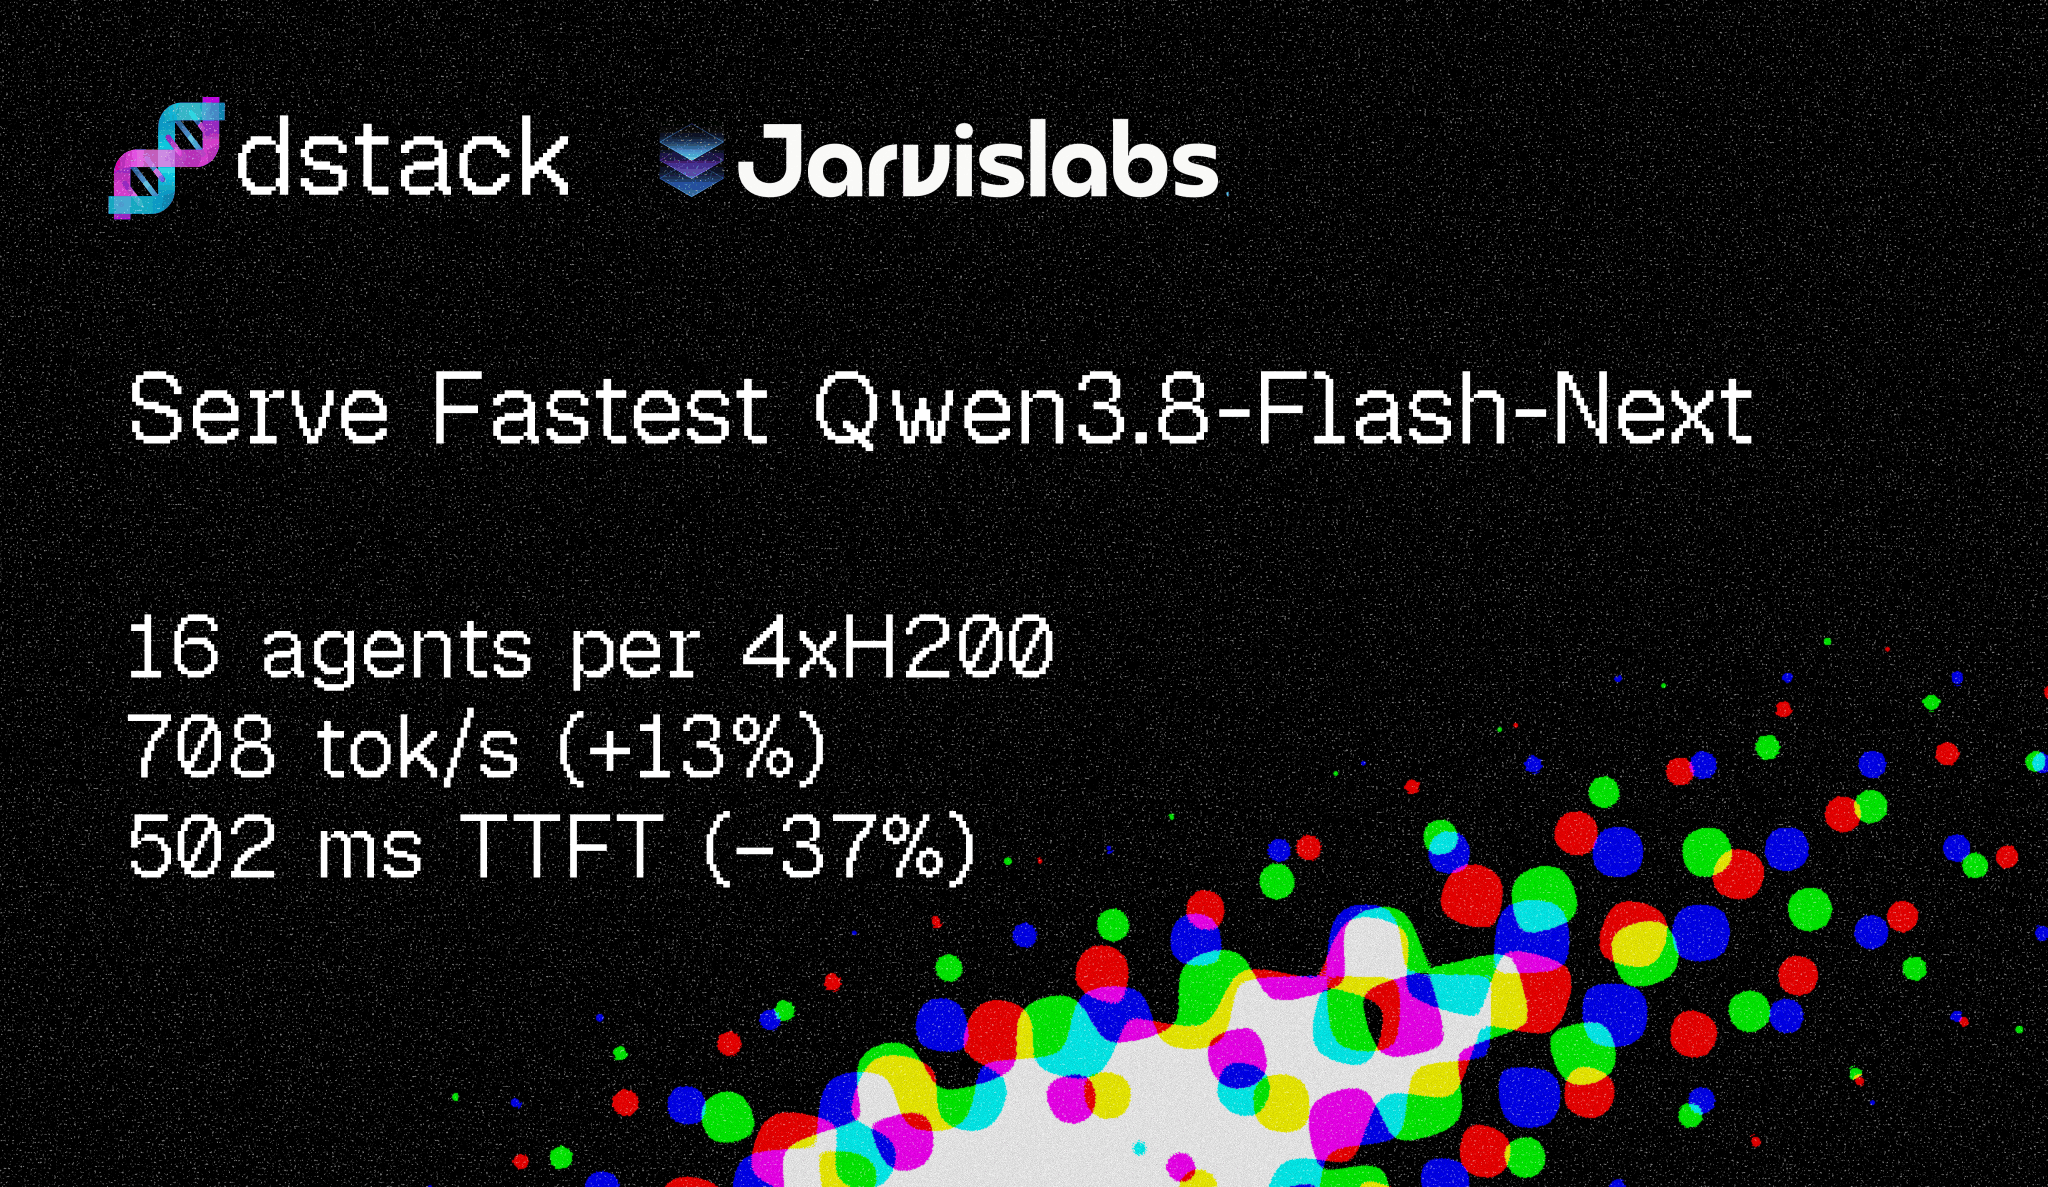
Serve Fastest Qwen3.8-Flash-Next Coding Agents on 4xH200

When optimized using dstack's presets, 4xH200 can serve 16 concurrent coding agents, with roughly 3x lower latency than the available providers. By a coding agent we mean one session of a tool like Claude Code: a multi-turn conversation with its own context of 100–150k tokens, which pauses between turns while it runs tools or waits for the user and sometimes spawns subagents.
This work was made possible through the generous support of our partners at Jarvislabs, who provided access to the compute.
Presets: a toolkit for agent-based inference optimization

Optimizing model inference is agent work now. Every inference provider does it inside its own process, on its own serving stack, with its own harness around the optimization agent. Despite the progress in open-source serving frameworks, what gets published is a benchmark, often without the workload, the concurrency, and the hardware behind it. The optimized deployment itself stays tied to the stack that produced it.

Today we're introducing a preview of presets: an open-source toolkit that streamlines inference optimization with agents, and a portable preset format.

Deploying NVIDIA Dynamo PD disaggregation with dstack

dstack is an open-source, AI-native orchestrator that works across clouds, Kubernetes clusters, on-prem fleets, hardware vendors, and frameworks. Alongside training, inference is one of the primary use cases dstack supports out of the box.

With the latest update, dstack added native support for NVIDIA Dynamo with Prefill-Decode (PD) disaggregation, letting a service run a Dynamo router, prefill workers, and decode workers as separate replica groups.

Deploying inference endpoints with PD disaggregation on AMD GPUs

dstack is an open-source, AI-native orchestrator that works across clouds, Kubernetes clusters, on-prem fleets, hardware vendors, and frameworks. Alongside training, inference is one of the primary use cases dstack supports out of the box.

dstack recently added native support for Prefill–Decode (PD) disaggregation. It works with Shepherd Model Gateway (SMG) — a high-performance inference gateway evolved from the SGLang Router — on both NVIDIA and AMD, and with NVIDIA Dynamo on NVIDIA. This post walks through deploying it on AMD GPUs with SMG.

How Graphsignal uses dstack for inference benchmarking

In a recent engineering blog post, Graphsignal shared autodebug, an autonomous loop that deploys an inference service, benchmarks it, updates the deployment config, and redeploys it again. This case study looks at the team workflow behind that setup, and how dstack gives Graphsignal a common layer for GPU development, inference deployment, and benchmarking.

Model inference with Prefill-Decode disaggregation

While dstack started as a GPU-native orchestrator for development and training, over the last year it has increasingly brought inference to the forefront — making serving a first-class citizen.

At the end of last year, we introduced SGLang router integration — bringing cache-aware routing to services. Today, building on that integration, we’re adding native Prefill–Decode (PD) disaggregation.

dstack 0.20 GA: Fleet-first UX and other important changes

We’re releasing dstack 0.20.0, a major update that improves how teams orchestrate GPU workloads for development, training, and inference. Most dstack updates are incremental and backward compatible, but this version introduces a few major changes to how you work with dstack.

In dstack 0.20.0, fleets are now a first-class concept, giving you more explicit control over how GPU capacity is provisioned and managed. We’ve also added Events, which record important system activity—such as scheduling decisions, run status changes, and resource lifecycle updates—so it’s easier to understand what’s happening without digging through server logs.

This post goes through the changes in detail and explains how to upgrade and migrate your existing setup.